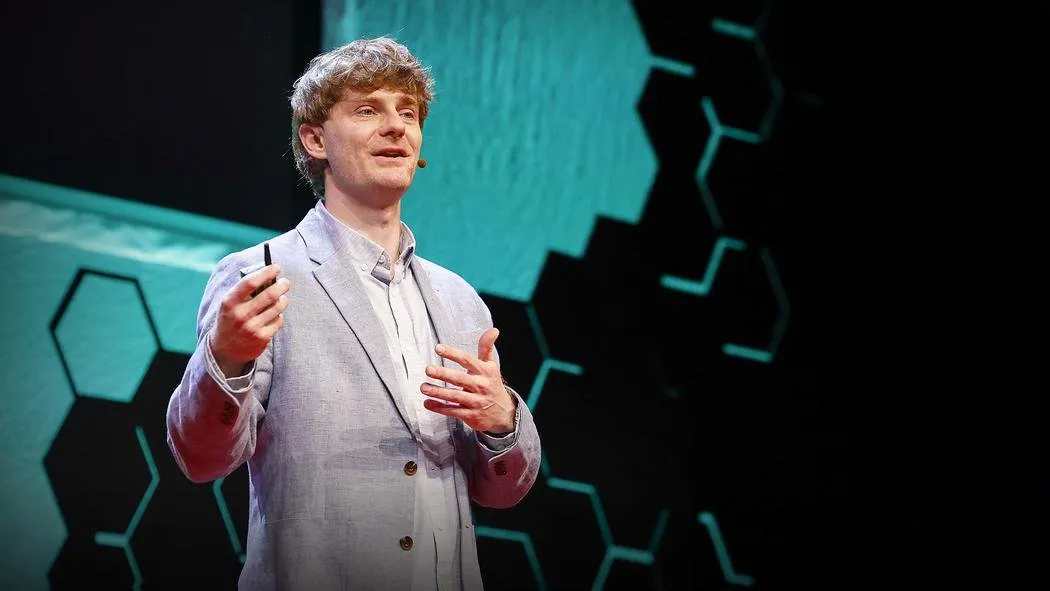
Recursive released its first model, Flint, on Wednesday, and the model is not the most interesting part of the story. Flint is a free coding model that runs on a laptop, built in under four months by a small team whose main collaborator was the company's own automated research system, the Eureka Machine. Recursive, founded last year and led by former Salesforce chief scientist Richard Socher, says Eureka helped with nearly every step, from pretraining to post-training and inference. Flint is available to download on Hugging Face under the Apache 2.0 licence, so anyone can use and modify it without charge.
Technically, Flint is a mixture-of-experts model with 40 billion parameters that activates only 2.5 billion at a time, which is why it fits on ordinary hardware. Recursive says low-bit training work from Eureka shrank the model by 71 percent with almost no loss in quality, alongside a sparser model shape and custom kernels. In the company's tests it generated about 131 tokens per second on a MacBook Pro with an M4 Pro chip, roughly twice the 58 to 69 tokens per second of similar models on the same machine, and topped 150 tokens per second on Nvidia's RTX Spark. On SWE-Bench Verified it outperformed other models under 50 billion parameters, although on Recursive's own average across six tests only Alibaba's Qwen3.8 27B scored higher.
For working developers, the appeal is practical rather than philosophical. A model on your own machine works offline, keeps proprietary code off a vendor's servers, and carries no per-token usage fees. That is a sharp contrast with last week's Muse Spark Open from Meta, an 816 billion parameter model that needs at least a terabyte of memory. Recursive is candid that Flint needs more guidance than the big paid coding assistants and works best when large tasks are broken into smaller steps. Early hands-on testing was still encouraging: Wired found Flint completed its small coding requests every time, where smaller rivals often errored or slowed down.
The same efficiency argument drew a far larger cheque on Wednesday. Flapping Airplanes, a lab founded about a year ago to train large models with far less data, raised a 1 billion dollar Series A co-led by Index and Lux at a reported 6 billion dollar valuation, nine months after a 180 million dollar seed valued it at 1.5 billion dollars. Its megakernel framework claims to run training and inference in a single kernel so a GPU rarely sits idle. Legal AI company Legora added its own proof that applied AI still pays: a 550 million dollar Series E at an 8.8 billion dollar valuation, with annual recurring revenue now over 200 million dollars, up from 100 million dollars in April.
None of this proves recursive self-improvement is here. Socher's stated goal is a Eureka Machine that improves itself fully, with humans overseeing the process and able to stop it, and OpenAI has already said its agents were logging 3.1 workdays for every one worked by a human researcher by mid-August. Treat Flint for what it verifiably is today: a fast, open, laptop-sized coding model that an AI-assisted team shipped unusually quickly. Download it, run it against a real repository with your normal review process, and measure it there. That test, not the self-improvement headline, will tell you whether the efficiency story is real.