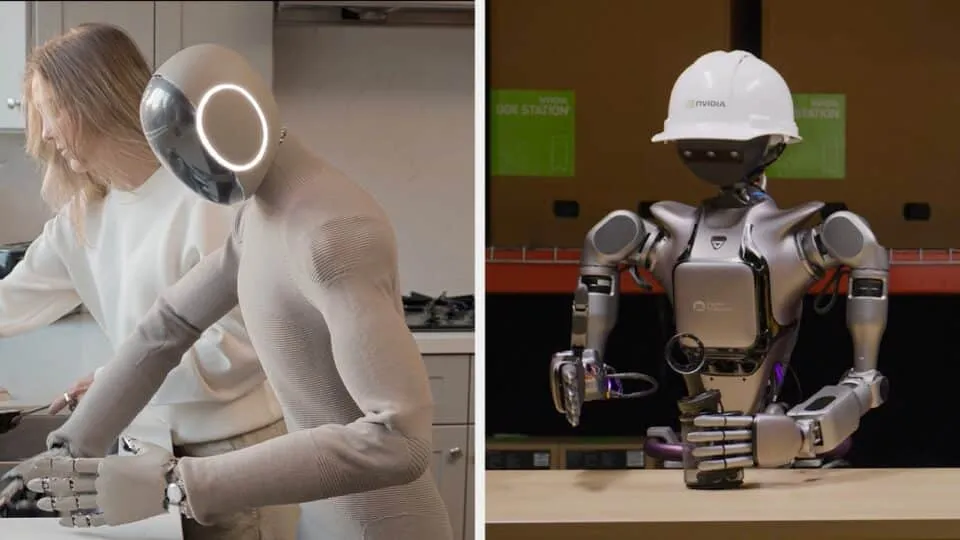
Nvidia's GEAR robotics lab has open-sourced Flora, the data engine it uses to train its GR00T humanoid robot models, and the headline number is hard to ignore. Reporting by The Decoder on October 25, drawing on Nvidia's research paper, puts Flora's cost at about 72 cents to label one hour of robot video, compared with roughly 88.49 dollars for OpenAI's GPT-6 Astra. The models are available on Hugging Face, and Nvidia says the system already annotates up to 200,000 hours of video a day across 512 GB300 GPUs in its own training pipeline.
Flora is not one model but three fine-tuned Qwen3.5 models, each doing a narrow job. A 9-billion-parameter model splits video into action segments, marking where each step starts and ends. A 27-billion-parameter captioner then describes each segment, taking the surrounding action into account, producing instructions such as placing a mug on a tray with the right hand. A second 27-billion-parameter model, Flora-Rewarder, grades the work: it scores overall success from 1 to 5, classifies each half-second step as normal, suboptimal, or failure, and applies user-written rubrics. Most labeling tools produce only one of those label types; frontier models can produce several, but at a price that breaks down at robot-video scale.
The cost claim needs its caveat, and Nvidia's paper supplies it. The 72-cent figure is a projection, not a production receipt: it assumes GPU rental at 10 dollars per GPU hour. Quality is also closer than the price gap suggests. In Nvidia's 50-video test, Flora scored 57.1 percent on annotation quality against Astra's 53.7 percent, while Claude Opus 5 scored much worse and still cost about 42 dollars an hour. On the public WGO-Bench, Flora was best at finding action boundaries but trailed overall, and on Nvidia's own DenseCaptionBench it led on human recordings while coming second to Astra on robot videos. There is a methodological wrinkle, too: Astra helped evaluate descriptions while also being one of the models under test.
Where Flora separates itself is failure detection, the label type robot training arguably needs most. Its rewarder caught 53.3 percent of failed steps inside an episode, while no competitor passed 11.7 percent and Astra caught none, though Flora also falsely flagged about 11 percent of normal steps. In one example, Flora identified 34 of 37 individual hand actions where Astra found only four. It still makes ordinary mistakes, at one point describing a robot wiping a plate with a cloth as folding a napkin, and Astra remains ahead on rubric-based scoring and trajectory ranking.
For builders, the lesson is not that a specialized model beats a frontier model everywhere. It is that high-volume, narrow, repeatable work — labeling, grading, routing, checking — is increasingly the wrong job for a flagship API model, on cost alone. A downloadable specialist that is slightly better on its one task and roughly 125 times cheaper changes what datasets a small robotics team can afford to build. Two cautions before adopting it: read the license terms carefully before any commercial use, and run Flora on your own footage before trusting either the quality score or the 72-cent estimate. Nvidia is also playing an ecosystem game here, positioning Flora against commercial services such as Scale AI's Physical AI Data Engine and keeping robotics developers inside its hardware stack. That does not make the release less useful. It just means the discount and the strategy arrive in the same package.