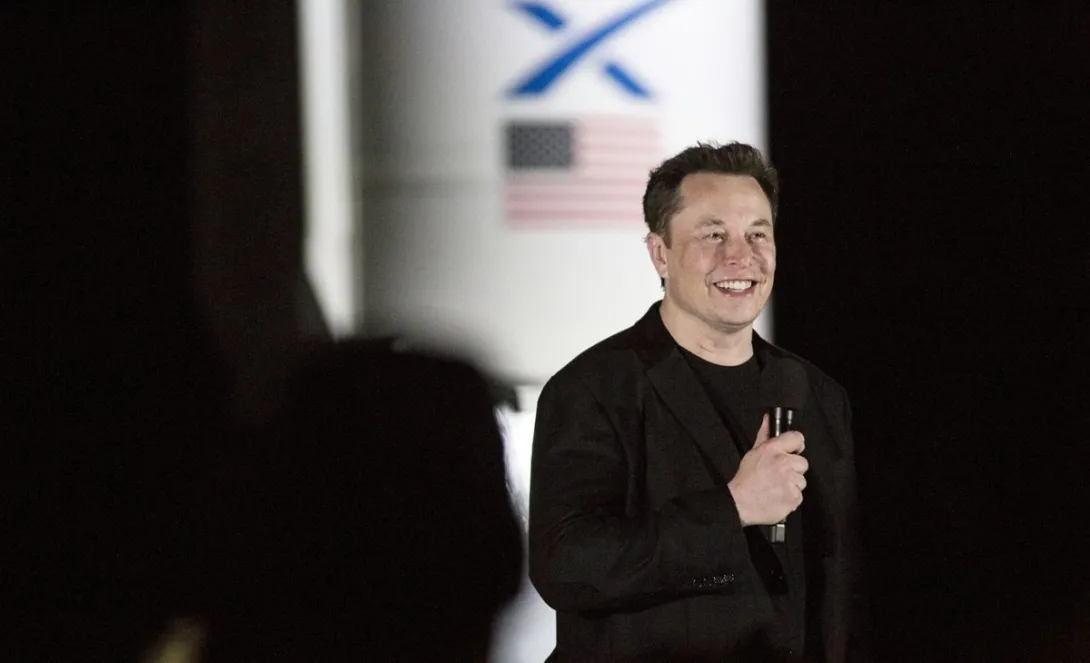
Over Halloween weekend, some Grok Bot users found their weekly usage limits maxed out, even though they had not been using SpaceX's agentic AI overnight. Users on X reported usage jumping from as low as 50 percent to 100 percent. On Sunday, November 1, SpaceX CEO Elon Musk confirmed in a reply on X that this was not a glitch. "The cost of serving Grok Bot was unsustainably high relative to revenue," he wrote, according to TechCrunch's November 2 report. Musk has not yet said how subscribers' limits will change from here, leaving paying users with a product whose allowance can be revised downward without warning.
The striking part is that Grok Bot is not a failing product. SpaceX said in a filing last month that AI now makes up 52 percent of company income, and its renamed Super Intelligence division turned a profit of 431 million dollars, a rarity in this industry. That profit would have been higher without 1.2 billion dollars of one-time costs tied to its acquisition of Cursor, and Musk has called Grok Bot the fastest-growing product he has ever seen. The throttle was applied to a successful product because agentic usage scales costs faster than subscription revenue: an agent working overnight burns inference the whole time, whether or not the user ever sees the bill.
For anyone building with AI, this is the unit-economics lesson of the week, arriving from the top of the market. A flat-rate agent product carries open-ended inference liability — every extra tool call, retry, and long-running task is your cost, not your customer's. The defenses are unglamorous: meter by task rather than by seat, cache aggressively, route routine work to smaller models, and put hard per-task budgets in the code rather than in the terms of service. OpenAI's move to draw ChatGPT and Codex from one shared token pool, reported yesterday, is the same pressure from the other side. When even a profitable division at SpaceX's scale pulls back limits in public, smaller builders should assume their margins are thinner than their dashboards suggest.
The day's funding news showed how differently claims get priced. Israeli startup 42AI came out of stealth on November 2 with 62.5 million dollars in seed funding for a behavioral world model meant to predict how a person will decide in a new situation, starting with traders at brokerages. It says it works with 10 large brokerages, is generating more than seven figures in revenue, and claims one brokerage gained about 30 million dollars through dynamic hedging. Read the accuracy claim carefully: the 98 percent figure measures whether trading flows fell within a predicted range, not whether each trade was predicted, and the seed came largely from the founders and Infinity Group over three years, not entirely from outside investors.
Finally, Omen AI, founded in 2024 to build real-time sensors for data-center cooling fluids, is acquiring competitor Aquatic Labs in a 16 million dollar cash-and-stock deal, after a 31 million dollar Series A in June. United States data centers use 17 to 19 billion gallons of water a year for cooling, a figure The Water Foundation expects to triple within five years, and operators who cannot monitor that fluid in real time often dump it and shut down rather than risk their hardware. Omen expects its sensors to be monitoring 250 to 300 megawatts of chips by year's end. The theme is consistent: AI is now being priced on serving costs, prediction quality, and cooling water — the measurable parts — and the builders who measure earliest will still be standing when the limits get rewritten.