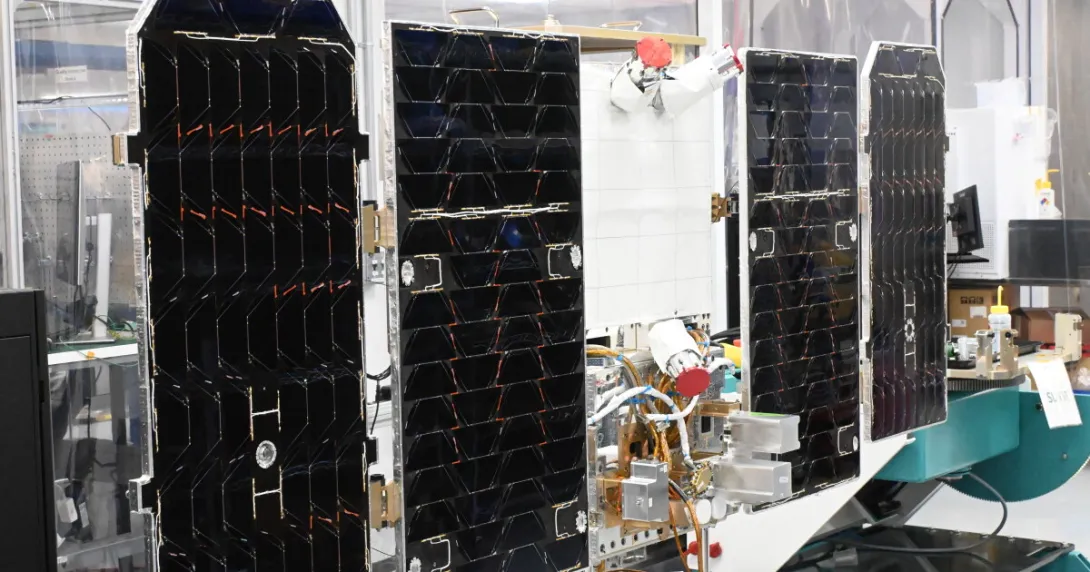
Google has received its first AI answer from orbit. The company said on October 30 that its Project Suncatcher prototype satellite booted a data-center-class Tensor Processing Unit, ran a prompt on the onboard Gemma 4 open model, and downlinked the reply to Earth. The prompt, uplinked during a ground-station pass, asked for a haiku about being in space, and the answer came down as the satellite passed over Svalbard, Norway: Blue marble below, data streams in silent grace, starlight feeds my core. Chief executive Sundar Pichai called it a hello world milestone. Google followed with limericks and prompts asking the model to report the payload's status, and a spokesperson told TechCrunch the satellite is operating nominally.
The hardware behind the poem is deliberately modest. The satellite, built with Planet, launched on October 1 aboard a SpaceX Falcon 9 rideshare and carries four TPUs, but its solar panels generate only up to 1 kilowatt, so just one chip can run at a time, for about 20 minutes per session. Roughly three weeks of commissioning came first, powering up the host and the TPU trays and running early tests, before the first prompt was attempted. Project Suncatcher, announced in November 2025, is Google's long-term bet that near-constant sunlight in orbit could one day power machine-learning infrastructure that is increasingly hard to site, power and cool on the ground. Google is explicit that this is research aimed at the 2030s, not a product.
What Google still has to prove is durability. The next phase tests how the TPUs handle thermal stress and radiation, and radiation is the serious risk: a particle strike can flip a stored bit and corrupt a result silently, tolerable in a poem and unacceptable in paid inference. In earlier laboratory work with a proton beam, Google researchers found the chips' high-bandwidth memory the most sensitive component and estimated a failure probability on the order of one per 3 million inferences for typical transformer workloads, likely acceptable for inference. If the orbital tests go well, two further satellites are planned for 2027, linked by laser optical communications so Google can test whether separate spacecraft can work as one system.
For builders, the honest reading is that this is a boot test, not a benchmark. Google published no figures for speed, cost or chip lifetime in orbit, and one chip running 20 minutes at a time answers no capacity question anyone is asking this year. What it does establish is narrower: a standard AI accelerator survived launch, powered up in orbit and completed a full prompt-to-answer round trip under real power constraints. The constraints are the story. Inference is becoming a placement problem as much as a model problem, decided by available power, cooling and permission to build, and Suncatcher is one lab's attempt to learn, early and cheaply, whether orbit belongs on that list at all.
The same week offered the opposite philosophy from Apple. In a Wired interview published October 30, Apple chief executive John Ternus, who took the job in September, defended the company's slower pace: Apple is absolutely going to leverage AI, he said, but we don't want to ship AI for AI's sake, and done right, people will not have to think about whether AI or traditional software made a feature happen. Pressed on whether agents could make apps unnecessary, he called creating products a deeply human and personal thing. Between a haiku from orbit and a chief executive arguing AI should be invisible, the week framed two live questions: where computation can physically live, and whether users should ever notice it is there.