Skip to header Skip to main navigation Skip to main content Skip to footer

DeepSeek's New Flash Model Cuts the Cost of an Agent Task to Under 20 Cents

Breadcrumb

  • Home
  • DeepSeek's New Flash Model Cuts the Cost of an Agent Task to Under 20 Cents
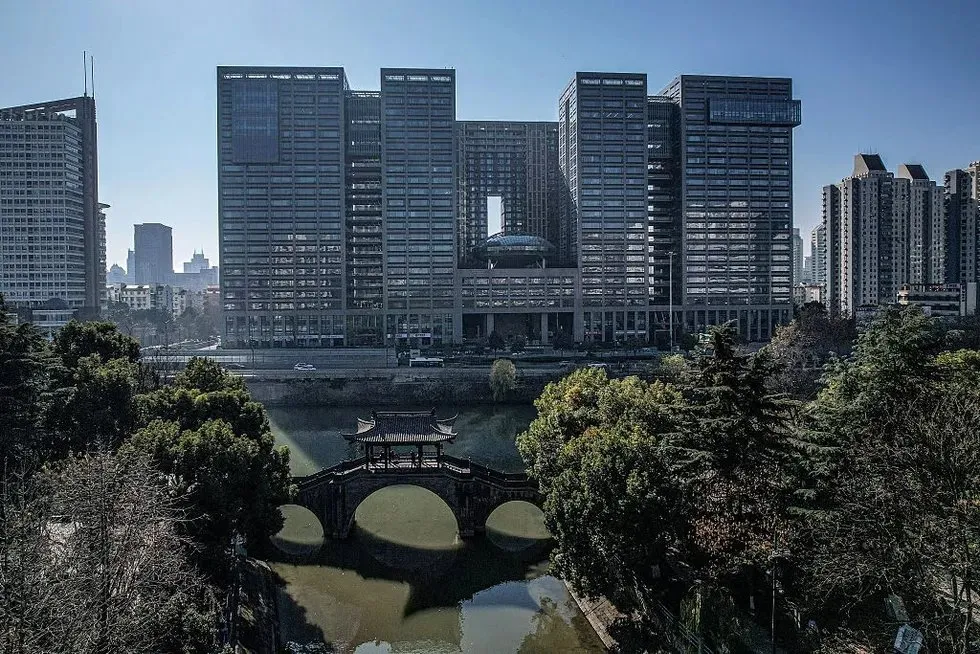
Aerial photograph of the modern office towers housing DeepSeek's headquarters across a river with an arched bridge in the foreground.

DeepSeek shipped an updated Flash model on October 17, and the headline is not raw intelligence but price per finished task. DeepSeek-V4.1-Flash-1017 is live now on the company's website, in its app, and through its API, with open weights published on Hugging Face and ModelScope. DeepSeek calls the release a Pareto improvement over the V4.1-Flash it replaces: better benchmark scores, faster responses, and shorter outputs at the same time, which is the combination that actually moves an agent workload's bill.

On DeepSeek's own DeepSWE v1.1 chart, run on the mini-swe-agent harness, the new model reaches 77.0 percent at an average cost of just under 20 cents per task, and still clears 72 percent in its low reasoning setting for about 10 cents. Its predecessor scored 74.2 percent at roughly 50 cents a run. Rival models in the same chart, including GPT-6 Astra, Gemini 3.8 Flash, and Claude Opus 5, land between 2 dollars and more than 10 dollars per task without matching that score. DeepSeek also reports wins over Opus 5 on agent-heavy tests such as Agents' Last Exam, 35.4 to 28.6, and Automation-Bench, 60.5 to 50.3. Treat those numbers as vendor claims for now: independent benchmarks have not appeared yet, and Opus 5 still leads clearly on raw reasoning tests like Humanity's Last Exam.

The engineering behind the gain is mostly about wasting fewer tokens. For building complete software projects from scratch, DeepSeek used reinforcement learning with self-feedback, letting the model train on its own confidence scores and self-generated critiques instead of human evaluators or a separate reward model. Shorter, more decisive outputs are what turn that training into the cost curve above. The model is tuned for agentic coding environments including DeepSeek Harness, where version v0.2.1-rc.1 or later is recommended, plus Tencent's CodeBuddy and WorkBuddy.

DeepSeek also opened a second front this week: its in-house web search is now a public product. The new Search and Fetch APIs cost 0.75 dollars per 1,000 calls, run on an engine DeepSeek says already handles hundreds of millions of queries a day, and are free through server-side tools in DeepSeek Harness, Claude Code, and Codex until October 31. That makes DeepSeek not just a model vendor but an infrastructure supplier for other people's agents, search included.

Cheap agents will still hit a gated web. Reporting by The Verge on October 17 found major sites closing their doors to AI agents: Yelp admits only agents paying for its data licensing program, Delta Air Lines blocks agent ticket booking, and JPMorgan Chase and Charles Schwab block agent account access over security concerns, while Shopify has opened its storefronts to agents. The practical lesson for builders is twofold. Test Flash-1017 on your own agent evals before believing any leaderboard, and design for a web that increasingly charges agents for entry or refuses them outright. The model is getting cheaper; access is becoming the scarce resource.
DeepSeek
Open Weights
AI Pricing
Large Language Models
AI Product News
Frontier Models
Rocky Mountain Madman LLC

Ai Industry News

Jev Broke Vercel's Adoption Record by Doing Less: The Rise of the Decision Model

Vercel's October AI Gateway Production Index, published Thursday and reported by TechCrunch on October 16, contains a result that should recalibrate what builders think a winning model launch looks like. Jev, a small decision model from TypeSafe AI released in limited form in September, reached 35.3 percent of paid teams on Vercel's AI Gateway in its first two weeks, nearly double the 18.1 percent reach of Anthropic's Sonnet 5.5 in second place.

  • Read more about Jev Broke Vercel's Adoption Record by Doing Less: The Rise of the Decision Model

Simons, OpenAI and Anthropic Put 15 Million Dollars Behind Checking AI Math

Cartoon illustration of robot mathematicians in a mountain workshop checking glowing scrolls of abstract geometric shapes with magnifying glasses.

On October 15, the Simons Foundation announced a partnership with Anthropic and OpenAI committing 15 million dollars in combined funding and resources to help mathematicians navigate the rapid rise of AI in their field. The foundation will manage and award the money, including through an open call for proposals, supporting workshops and programs where researchers evaluate recent AI-assisted results, learn new tools, share perspectives, and shape collective standards for AI use.

  • Read more about Simons, OpenAI and Anthropic Put 15 Million Dollars Behind Checking AI Math

Meta's Muse Spark Open Puts an 816-Billion-Parameter Model on Two Macs

Cartoon robot engineer linking two desktop computers beneath a glowing puzzle-piece brain in a mountain workshop

Meta released Muse Spark Open on Thursday, October 15, calling it the most capable United States open-weight model to date. That is a vendor claim, and independent testing will settle it, but the release itself is the news: after focusing on its closed Muse Wonder models earlier this week, Meta has put a frontier-scale model into downloadable weights that developers can host, inspect, and adapt outside Meta's own service.

  • Read more about Meta's Muse Spark Open Puts an 816-Billion-Parameter Model on Two Macs

Pagination

  • First page « First
  • Previous page ‹ Previous
  • Page 1
  • Current page 2
  • Page 3
  • Page 4
  • Page 5
  • Page 6
  • Page 7
  • Page 8
  • Page 9
  • …
  • Next page Next ›
  • Last page Last »

Copyright © 2026 Rocky Mountain Madman LLC - All rights reserved

Developed and Designed by Rocky Mountain Madman LLC