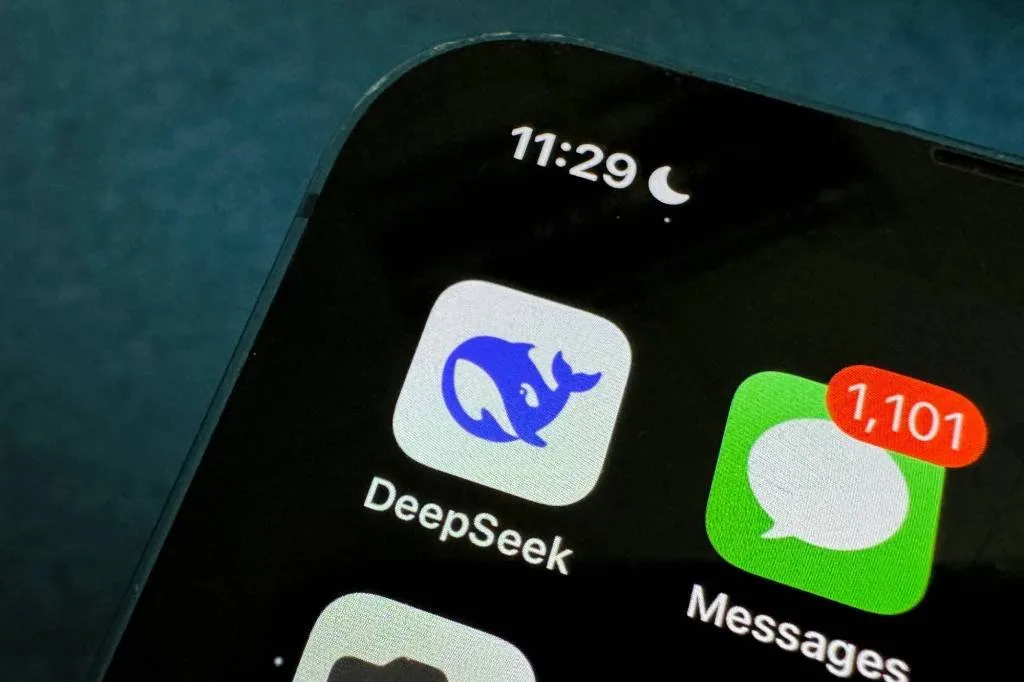
DeepSeek has reportedly raised about 15 billion dollars, roughly 100 billion yuan, in one of the largest funding rounds ever completed by a Chinese AI company. TechCrunch, citing Bloomberg, reported the raise on Thursday morning, just two days after the United States ordered federal civilian agencies to remove DeepSeek technology from their systems over security concerns. Battery maker CATL and Tencent, the company behind WeChat, were named among the investors. DeepSeek did not immediately respond to a request for comment, so the round should be read as reported rather than confirmed by the company itself.
The numbers behind the story explain the investor appetite. The Wall Street Journal, via PYMNTS, put DeepSeek at about 74 billion dollars before this round and said demand nearly doubled the original target. That follows a June round of more than 7 billion dollars at a 50 billion dollar valuation. Founder Liang Wenfeng reportedly told investors in September that annualised revenue had reached 1 billion dollars, more than double the 400 to 500 million dollar run rate reported in July, driven mainly by paid API access. The Journal also reported gross margins of 70 to 80 percent on the flagship V4 model, even though DeepSeek charges less than its American rivals, helped in part by peak-hour pricing introduced in August that raised flagship rates roughly fourfold.
That margin claim is the real challenge to the frontier labs. The standard assumption in this industry is that competitive models require ruinous spending and that low prices mean low or negative margins. DeepSeek built its reputation in early 2025 on an open-weight reasoning model that embarrassed far better funded rivals, and it is now using fresh capital to expand domestic computing infrastructure and reduce dependence on foreign chips. It still uses Nvidia processors for its most complex training, according to the Journal, while working with Huawei to move more workloads onto Chinese chips. A planned Shanghai listing in early 2027, advised by Citic Securities, would force the first public test of whether the low-cost strategy produces durable profits.
A different kind of opening happened in American retail this week. Walmart announced an Agent Gateway, its own MCP server, that lets approved AI agents search its inventory and buy on behalf of customers at Walmart and Sam's Club, TechCrunch reported on Wednesday. Agent Profiles, rolling out next month, give each agent a dedicated profile linked to the customer's account, with purchases shown separately, approval required for each transaction or a spending limit set in advance, no access to payment information, and the normal returns process applying even when an agent acts unexpectedly. Agents that break Walmart's terms will be blocked. Amazon, by contrast, has begun blocking outside agents from buying on its site.
For builders, these two stories are the same lesson from opposite ends. Access is being formalised, not abolished. Capital is still reaching a restricted Chinese lab because its efficiency numbers look credible, and a major retailer is welcoming agents, but only through an identified gateway with scoped permissions, spending controls, and an audit trail. Evaluate DeepSeek's models on their merits, with a serious security and compliance review before any production use, and design your own agent integrations the Walmart way: named agents, least-privilege access, approval gates for money movement, and logs you can actually inspect. That is the architecture that survives contact with regulators, customers, and reality.