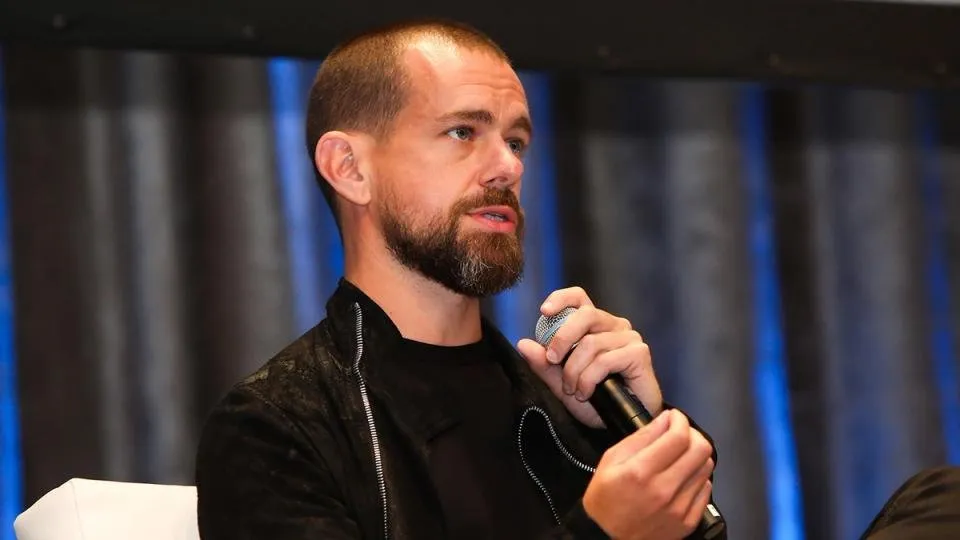
Jack Dorsey's Block released a voice model this week that takes the opposite bet from almost everyone else in speech AI. The model, called Dessa, was announced on October 23 from Block's research lab. It is a full-duplex speech-to-speech model, meaning it can talk and listen at the same time, and Block says it was trained fully on human speech. There is no text pipeline in the middle. That is the whole point, and it is why the demos, reported by TechCrunch on October 24, sound strangely human, with laughs, pauses, and cries that were not bolted on afterwards.
Most voice systems convert your speech to text, run a large language model over that text, then convert the answer back to speech. Block argues that pipeline throws away exactly the information that makes a conversation feel real. In its blog post the company put it bluntly: interacting with current voice AI can just plain suck, because turning voice into text discards how someone feels. Rivals such as ElevenLabs and Fish Audio lean on voice tags to steer emotion. Block claims Dessa's emotion is built into the model itself, so when a demo voice says it is tired from work, it actually sounds tired. Whether that holds up outside curated examples is the open question, but the architecture choice is real and different.
The practical claim matters as much as the demos. Block says Dessa can run locally, on a single NVIDIA GPU and on consumer-grade hardware such as a MacBook M4 Max or better, rather than requiring a cloud round trip for every utterance. For a company that sells Square point-of-sale tools to small businesses, and already uses voice AI to handle ordering, an on-device model changes the cost and privacy calculation. A shop could in principle run a conversational agent on premises, with lower latency and no per-minute cloud speech bill. There is no public access yet, and Block has put out a call for safety researchers to test it first, a sensible pause for a model convincing enough to trick someone on the other end of a call.
Google Cloud used AGNTCon and MCPCon on October 22 to unveil Agent Compute Engine, which gives each agent its own hardware-isolated microVM, keeps the harness that calls the model entirely outside the sandbox, and holds no credentials inside that sandbox at all. Google says the service already powers Gemini as an agent for work tasks, with a customer preview in the coming months and an open-source sibling, Agent Substrate, for Kubernetes. AWS and UC Berkeley, meanwhile, open-sourced Infinity, a runtime that suspends an agent while it waits on a tool call and resumes it when the result arrives, at roughly 100 kilobytes per idle agent in its test, so long-running agents do not burn compute while they wait.
Together, the week points one way: intelligence is moving out of the generic cloud chatbox and into the place where the work actually happens, locally, sandboxed, or suspended until needed. For builders, that means evaluating voice and agent products on different questions than a year ago. Not just how smart is the model, but where does it run, what credentials can it touch if it is prompt-injected, what does it cost while it waits, and what information does its pipeline discard before it ever answers. Dessa may or may not prove the speech-only bet. The questions it forces are the right ones, and they now apply to every agent you ship.