Skip to header Skip to main navigation Skip to main content Skip to footer

Apple Puts Alibaba's Qwen Inside the iPhone in China: One Product, Two AI Engines

Breadcrumb

  • Home
  • Apple Puts Alibaba's Qwen Inside the iPhone in China: One Product, Two AI Engines
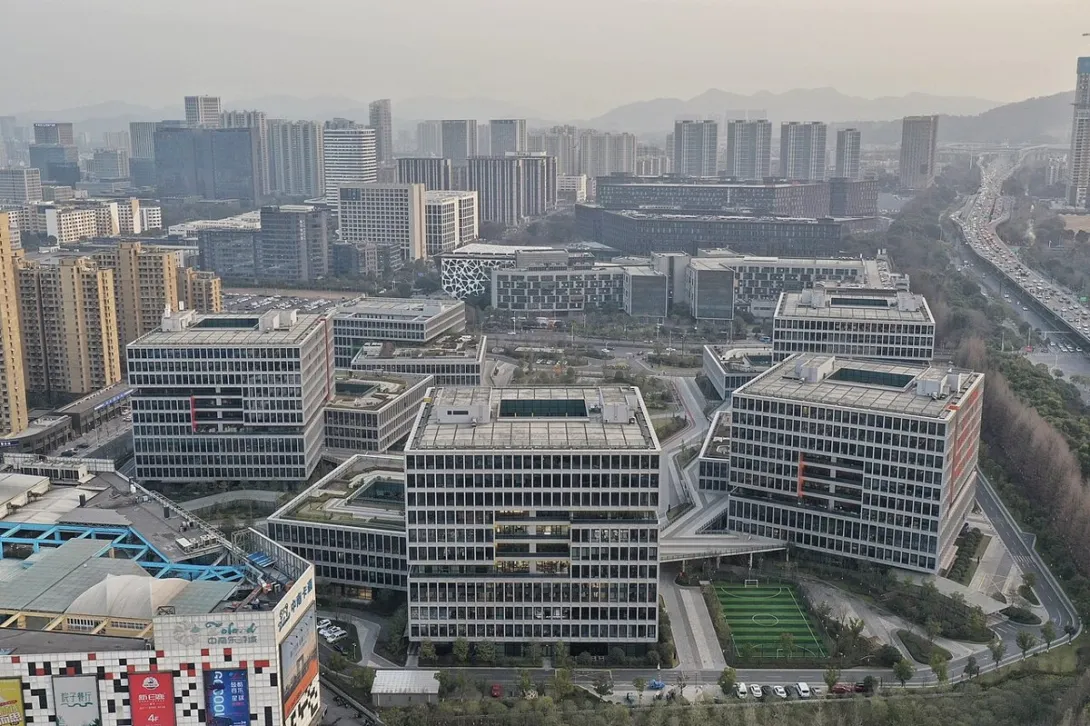
Aerial photograph of the Alibaba Center campus buildings in Binjiang, Hangzhou, surrounded by city towers

Apple Intelligence is finally coming to iPhones in mainland China, and it will not run on the same outside model Apple uses elsewhere. Apple confirmed on its China newsroom on October 31 that testing begins November 4 in the next iOS developer beta, with a public launch in December as part of iOS 27.3. Alibaba announced the same day that its Qwen model will power parts of the experience. Two years after Apple Intelligence was unveiled in 2024, the China version arrives with a local partner, a local model, and a feature set shaped by local approval.

In China, users will be able to reach Qwen from Siri for certain requests, from Writing Tools, and from Visual Intelligence, covering text and image understanding and content generation. Writing Tools gains a compose option that lets Qwen draft original text from scratch, and Visual Intelligence can answer questions about photos and documents, including PDFs and presentations, after users sign in with a Qwen account or Sign in with Apple. The first wave also includes Live Translation, Genmoji, Clean Up in Photos, natural-language photo search, notification summaries and Smart Reply. What it does not include matters just as much: Siri AI and the other next-generation features announced at WWDC 2026 stay out, the rollout is iPhone-only for now, and it runs on the iPhone 15 Pro and Pro Max, iPhone 16 and later, iPhone Air and iPhone Duo, with device and Siri language set to English or Simplified Chinese.

Alibaba says participation is opt-in and that it will not use user requests or generated responses to train its models. Eligibility covers people who bought an Apple Intelligence-capable iPhone in China, or whose device location and Apple Account region are both set to China. The timing follows a long regulatory path: in July, China's cyberspace authority completed the filing for Apple Intelligence among seven on-device generative AI services for smartphones. In other words, the model swap was not a product preference. It was the price of entry.

For builders, this creates a clean two-engine world. The same Siri, Writing Tools and Visual Intelligence surfaces will behave differently inside China because a different model sits behind them, with different strengths in language, tone and edge cases, and the app does not get to choose which engine answers. Anyone shipping for users in both markets should use the November 4 beta to test Writing Tools in Simplified Chinese across formal and casual registers, and Visual Intelligence on real photos, documents and signs rather than demo images. Assuming identical output across regions is now a bug waiting to ship.

The same split is showing up in infrastructure politics. TechCrunch reported November 1, via Axios, that OpenAI is preparing a post-midterm public campaign in the United States, with chief global affairs officer Chris Lehane floating AI speed limits, global standards and rebranding data centers as AI compute campuses. Put the two stories together and the lesson is the same: frontier AI no longer ships as one global product. It ships market by market, under local rules, local partners and local names, and practitioners who plan for that fragmentation early will spend less time retrofitting later.
Rocky Mountain Madman LLC
AI Product News
China AI
Multimodal AI
Large Language Models
AI Policy

Ai Industry News

Mistral Goes Big: Large 4 "Le Chonk" Puts Europe on the Frontier Map

Cartoon illustration of a colossal friendly robot shaped like a mountain peak with glowing circuit patterns, towering over a stylized European cityscape at dusk.

Mistral has finally shipped a frontier-class model, and it is a statement piece. Large 4, immediately nicknamed "Le Chonk" by an internet that could not resist, is a natively multimodal mixture-of-experts model with 1.05 trillion total parameters and 49 billion active parameters, wrapped around a 1-million-token context window. It was trained from scratch on 3,800 Grace Blackwell GPUs in Mistral's own European datacenters — no rented American cloud, no borrowed infrastructure — and it is available right now as a public preview through Mistral's API.

  • Read more about Mistral Goes Big: Large 4 "Le Chonk" Puts Europe on the Frontier Map

Anthropic Slashes Haiku Pricing 90% as the Small-Model Price War Hits the Enterprise

Cartoon illustration of a cheerful robot mechanic tuning a row of small friendly robots at a workbench, with blank price tags floating in the air.

Anthropic released Claude Haiku 5.5 on October 7 with a price cut that rearranges the math of production AI work: about 90 percent cheaper than Haiku 4.5 on the prompts that matter. Short-context requests up to 100,000 tokens now cost 10 cents per million input tokens and 50 cents per million output tokens, with cache reads at a penny. Above the 100k line the discount drops to 50 percent.

  • Read more about Anthropic Slashes Haiku Pricing 90% as the Small-Model Price War Hits the Enterprise

Reflection AI's Beam: A 501B Open-Weight Bet on Efficient Reasoning

Cartoon illustration of a lighthouse beam made of glowing neural-network nodes rising from a small engine into a night sky.

Reflection AI has unveiled Beam, a 501-billion-parameter text-only mixture-of-experts model with just 23 billion active parameters, trained on 23.8 trillion tokens with a 1-million-token context window. The company's headline claim: Beam matches GLM-5.2 on reasoning while using three to four times less inference compute. The weights are expected later in October under Apache 2.0, once red-teaming wraps up. In a market obsessed with parameter counts, Beam is a bet that the number on the box matters less than the number actually doing work.

  • Read more about Reflection AI's Beam: A 501B Open-Weight Bet on Efficient Reasoning

Pagination

  • First page « First
  • Previous page ‹ Previous
  • …
  • Page 24
  • Page 25
  • Page 26
  • Page 27
  • Page 28
  • Page 29
  • Page 30
  • Current page 31
  • Page 32
  • Next page Next ›
  • Last page Last »

Copyright © 2026 Rocky Mountain Madman LLC - All rights reserved

Developed and Designed by Rocky Mountain Madman LLC