Skip to header Skip to main navigation Skip to main content Skip to footer

Anthropic's FlashProve Could Prove Which Model Answered You

Breadcrumb

  • Home
  • Anthropic's FlashProve Could Prove Which Model Answered You
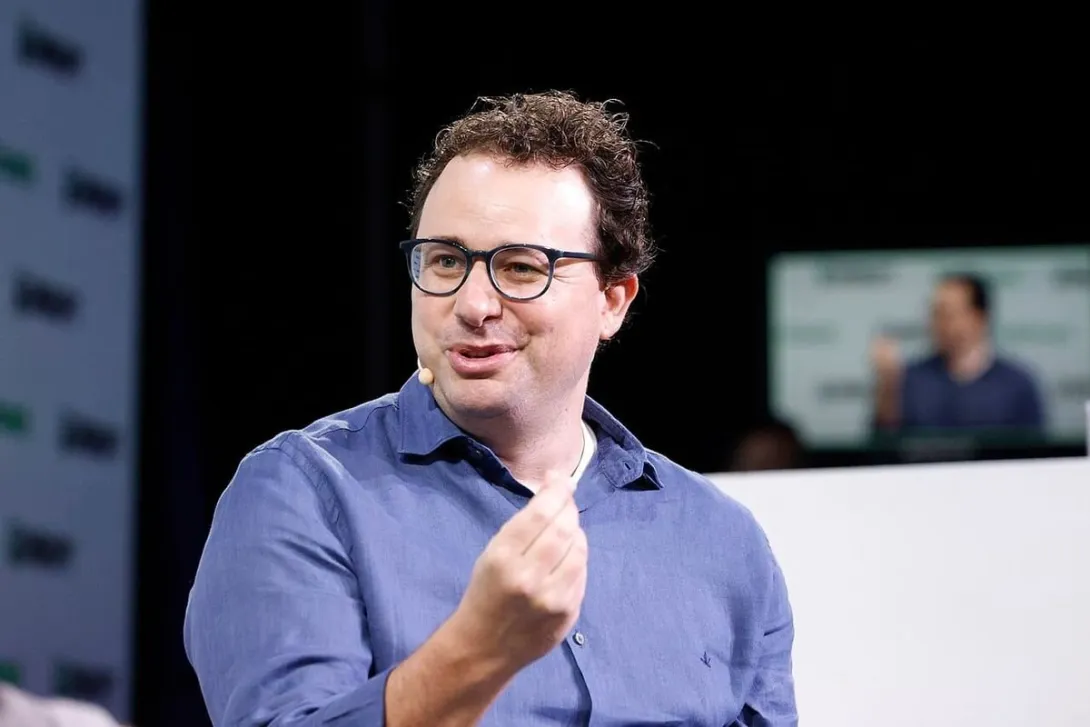
Anthropic CEO Dario Amodei speaking on stage at a TechCrunch event.

Anthropic published FlashProve on November 3, an open-source prototype for what its researchers call provable inference. The idea is simple to state and hard to do: when a model answers you, it should also produce a cryptographic proof that the answer really came from the specific model you were told you were using. TechCrunch reported the release the same day, and Anthropic released a technical report, a protocol specification, executable code and formal proofs under the Apache 2.0 license.

FlashProve works in two steps. A provider first publishes a commitment, a short fingerprint of one exact set of model weights, while the weights themselves stay private. Each response then carries a proof, built with a type of cryptographic proof known as a zkSNARK, that those committed weights produced those exact words. Anthropic tested the system on Meta's Llama 4 Maverick, a 400-billion-parameter mixture-of-experts model in 4-bit form. A single H100 GPU generated proofs at about 110 tokens per second, with a proof of about 19 megabytes for a 1,024-token request. Verification takes seconds, but proving takes about 70 to 95 times the GPU time of running the model itself.

That cost is why this matters as a direction rather than as a product. Anthropic says plainly that the research is intermediate progress, that there are no plans to deploy FlashProve at Anthropic or any other lab, and that others should take the work and improve it. The current prototype also covers only mixture-of-experts models, short contexts and a whole-number version of a model under greedy decoding. A user must still trust that a published commitment belongs to the model a lab says it does. None of that makes the underlying problem go away.

The problem is getting more commercial by the month. A routing service can quietly substitute a cheaper model, an attacker can tamper with a token stream, an evaluator can be shown a stronger model than customers receive, and a regulator can be told an approved model is running when it is not. Menlo Ventures, in its State of Enterprise AI report also released on November 3, estimated that enterprise AI deployment spending reached 176.8 billion dollars by September, up 5.4 times from 33 billion dollars a year earlier, and that agents now generate 80 percent of tokens on OpenRouter. When machines, not people, are most of the customers, a receipt for which model did the work stops being an academic curiosity.

For builders, the practical lesson is to start asking for receipts now, even before proofs this strong are affordable. Log the exact model identifier, provider and routing path for every consequential agent run, keep those logs where a client or auditor can inspect them, and treat any silent model substitution as a breach of contract rather than a routine upgrade. FlashProve will not run in production tomorrow at 70 to 95 times the cost of inference. But it shows that model identity can, in principle, be proved without revealing the weights, and that is the standard the largest buyers will eventually demand.
Anthropic
AI Safety
Enterprise AI
Large Language Models
Mixture of Experts
Rocky Mountain Madman LLC

Ai Industry News

DeepSeek Open-Sources a Super-Agent That Works Without Being Asked Twice

Photograph of the offices of DeepSeek in Beijing, showing modern glass office towers and a glass entrance pavilion.

DeepSeek's Harness team has published dsh-superagent-prototype on GitHub under the MIT license, a research prototype of a coding agent that does not wait to be prompted in a chat window. Released on October 31, with a design article, "Exploring Super-agent Design," following on November 1, the bundle for DeepSeek Harness listens to GitHub, and optionally to Feishu, and turns requests from authorized people into work items and pull requests.

  • Read more about DeepSeek Open-Sources a Super-Agent That Works Without Being Asked Twice

Apple Puts Alibaba's Qwen Inside the iPhone in China: One Product, Two AI Engines

Aerial photograph of the Alibaba Center campus buildings in Binjiang, Hangzhou, surrounded by city towers

Apple Intelligence is finally coming to iPhones in mainland China, and it will not run on the same outside model Apple uses elsewhere. Apple confirmed on its China newsroom on October 31 that testing begins November 4 in the next iOS developer beta, with a public launch in December as part of iOS 27.3. Alibaba announced the same day that its Qwen model will power parts of the experience. Two years after Apple Intelligence was unveiled in 2024, the China version arrives with a local partner, a local model, and a feature set shaped by local approval.

  • Read more about Apple Puts Alibaba's Qwen Inside the iPhone in China: One Product, Two AI Engines

Google's Suncatcher Satellite Answers From Orbit: A TPU Ran AI in Space

Photograph of the Project Suncatcher prototype satellite hardware with its solar panels in a Planet Labs clean room before launch.

Google has received its first AI answer from orbit. The company said on October 30 that its Project Suncatcher prototype satellite booted a data-center-class Tensor Processing Unit, ran a prompt on the onboard Gemma 4 open model, and downlinked the reply to Earth. The prompt, uplinked during a ground-station pass, asked for a haiku about being in space, and the answer came down as the satellite passed over Svalbard, Norway: Blue marble below, data streams in silent grace, starlight feeds my core. Chief executive Sundar Pichai called it a hello world milestone.

  • Read more about Google's Suncatcher Satellite Answers From Orbit: A TPU Ran AI in Space

Pagination

  • First page « First
  • Previous page ‹ Previous
  • Page 1
  • Page 2
  • Current page 3
  • Page 4
  • Page 5
  • Page 6
  • Page 7
  • Page 8
  • Page 9
  • …
  • Next page Next ›
  • Last page Last »

Copyright © 2026 Rocky Mountain Madman LLC - All rights reserved

Developed and Designed by Rocky Mountain Madman LLC